A software failure at JPMorgan Chase on November 16, 2026, delayed transactions involving the bank and created complications for some customers at other U.S. financial institutions, illustrating how a problem within one organization can affect interconnected payment systems. Although the disruption was not caused by a cyberattack, it exposed a significant business continuity concern: Organizations increasingly depend on technology systems they do not directly control.
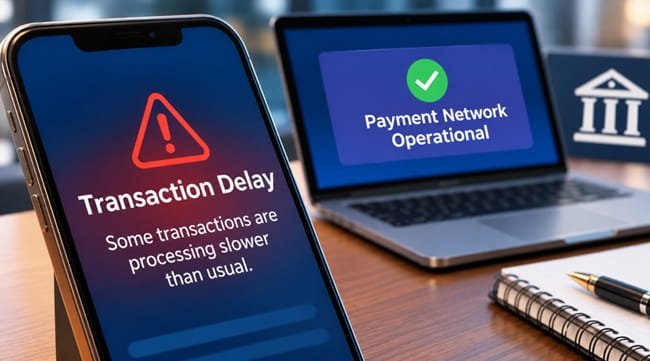
Customers reported problems involving Chase, Bank of America, Wells Fargo, U.S. Bank, and other financial institutions, while some users also experienced difficulties completing payments through Zelle. However, the apparent scale of the disruption requires an important distinction. Several banks reported that their own systems were operating normally, and Zelle confirmed that its payment network remained functional. Transactions involving Chase were delayed because of a technical problem originating within JPMorgan’s infrastructure.
The incident occurred during a week of other major technology disruptions involving Microsoft 365, the Federal Aviation Administration, and United Airlines. While these events were not established as connected, they highlighted the operational consequences of software defects, infrastructure failures, and dependencies between essential services.
For businesses, the central issue is not simply whether their technology is functioning. It is whether their operations can continue when an external system, payment provider, or critical application becomes temporarily unavailable.
What caused the November 16 JPMorgan Chase banking disruption?
JPMorgan Chase confirmed that the disruption originated from a software bug involving its on-premises hardware systems. According to Reuters, the bank reported that the technical issue was slowing transaction processing and affecting its ability to service some customers within normal timeframes. Chase stated that there was no evidence of cybersecurity-related activity and emphasized that the problem was not a systemic failure across the banking industry.
The distinction matters because early reports suggested that multiple major banks were experiencing simultaneous outages. Customer complaints appeared across several financial institutions, but the underlying technical circumstances were more specific. Transactions involving Chase could experience delays even when the other participating bank’s infrastructure was functioning correctly.
U.S. Bank confirmed that its systems were not directly affected, although customers attempting certain transactions involving other financial institutions could experience delays. Bank of America and Citigroup were also identified in reporting about transactions potentially affected by the Chase problem, without evidence that their own banking systems had suffered the same technical failure.
By Monday evening, Chase reported that transactions were processing normally again. The incident nevertheless demonstrated how quickly an isolated software problem can create widespread customer concern when financial institutions depend on interconnected payment and transaction-processing infrastructure.
Why Zelle payments were affected even though its network remained operational
One of the most significant aspects of the disruption involved Zelle, the digital payment service used by customers of more than 2,400 participating financial institutions. Reports of delayed payments led some users to question whether the Zelle network itself had experienced an outage.
Early Warning Services, the company operating Zelle, clarified that its network was functioning normally. However, customers access Zelle through participating banks and credit unions, meaning that technical problems within an individual financial institution can affect transactions even when the underlying payment network remains available.
This distinction illustrates a fundamental characteristic of interconnected technology. A transaction may depend on several separate systems completing their respective functions successfully. If one participant experiences a processing failure, the entire transaction can be delayed despite the continued availability of the other components.
Businesses encounter similar dependencies through payment processors, accounting platforms, enterprise resource planning systems, customer relationship management applications, and cloud-based software. A service may appear operational from a technical perspective while users remain unable to complete essential workflows because another connected system is unavailable.
Understanding these relationships is critical to developing realistic business continuity procedures. Organizations need to evaluate not only the availability of individual applications but also the dependencies required to complete business transactions.
The operational consequences of banking technology failures
Reliable financial systems are essential to everyday business operations. Organizations depend on banking platforms to receive customer payments, compensate employees, pay suppliers, manage cash flow, and reconcile financial records. When transaction processing becomes unreliable, the consequences can extend beyond the immediate delay.
A manufacturer waiting for a customer payment may experience uncertainty when scheduling supplier purchases or managing production expenses. A professional services firm may need to investigate whether an expected transfer has been completed before updating its accounts receivable records. Healthcare organizations, retailers, and other businesses may encounter administrative complications when payment confirmations do not arrive within expected timeframes.
These examples illustrate potential business consequences rather than confirmed outcomes of the JPMorgan incident. The actual operational impact depends on the duration of the disruption, the transaction involved, and the organization’s financial arrangements.
Nevertheless, payment-processing interruptions can create additional administrative work as finance teams verify transactions, communicate with customers, and reconcile records after normal service resumes. Organizations that depend on automated financial workflows may also need to determine whether delayed transactions will process automatically or require further attention.
Business continuity planning should therefore consider the consequences of temporary financial-service disruptions alongside more familiar scenarios involving network outages, unavailable cloud applications, or internal server failures.
Why managed IT services are relevant to business continuity
The JPMorgan incident originated within the bank’s infrastructure, meaning that an external business’s IT provider could not have prevented the underlying software failure. However, the disruption highlights why organizations need coordinated technology management and an understanding of the systems supporting their daily operations.
Businesses using managed IT services can establish more structured oversight of their technology environments through infrastructure monitoring, system maintenance, technical support, vendor coordination, and proactive IT management. These capabilities help organizations identify internal technology problems, maintain supported applications, and respond more effectively when operational disruptions occur.
The value of managed IT extends beyond troubleshooting individual devices or resolving employee support requests. A comprehensive IT management approach should also consider how business applications interact, which services are essential to operations, and what procedures are available when external platforms experience interruptions.
For example, an organization may rely on a cloud accounting application that exchanges information with its banking platform. If transaction updates are delayed, the IT team and finance department need to understand whether the problem involves the accounting software, the integration, or the external financial institution.
Without clear technical ownership and documented dependencies, businesses can waste valuable time investigating systems that are functioning correctly while the actual problem originates elsewhere.
Why interconnected systems require better visibility
Modern organizations increasingly use integrated technology environments designed to reduce manual work and improve operational efficiency. Accounting platforms exchange information with banks, CRM systems connect with billing applications, and cloud services support communication between employees, customers, and external providers.
These integrations provide substantial benefits, but they also introduce dependencies that may not be fully documented. When one system becomes unavailable, the consequences can spread through connected workflows, potentially affecting functions that appear unrelated to the original technical problem.
The JPMorgan disruption provides a practical example. A software issue within one bank affected transactions involving other financial institutions, creating the appearance of broader service failures. Organizations operating integrated business systems can experience similar situations when an application remains available but cannot exchange information with a required external service.
Technology teams should maintain accurate inventories of critical applications and document the integrations supporting essential workflows. This information should identify system owners, vendor responsibilities, data exchange methods, and potential operational consequences if an integration fails.
Visibility also improves troubleshooting because teams can distinguish between internal infrastructure problems and failures originating with external providers. This reduces unnecessary changes to functioning systems and supports more effective communication with affected departments.
Legacy infrastructure and software reliability remain critical concerns
JPMorgan attributed the November 16 disruption to a software bug involving on-premises hardware systems. Although the bank did not publicly establish every technical detail behind the defect, the incident illustrates that locally maintained infrastructure remains an important component of enterprise technology operations.
Cloud adoption has transformed business computing, but many organizations continue to operate combinations of on-premises servers, network equipment, specialized applications, and externally hosted services. These hybrid environments require careful maintenance because operational performance depends on compatibility between different technologies.
Software updates, configuration changes, hardware replacements, and infrastructure modernization projects can introduce unexpected problems if dependencies are not adequately understood. Organizations should therefore maintain disciplined change management procedures that include testing, approval processes, rollback plans, and post-deployment monitoring.
These practices are particularly important for businesses operating specialized or legacy applications that cannot be easily replaced. Healthcare organizations, manufacturers, and professional services firms may depend on established systems that support essential workflows but require additional attention to maintain reliability and security.
Modernization should be evaluated according to operational requirements rather than simply replacing older technology. The objective is to improve performance, reduce unnecessary complexity, and strengthen the organization’s ability to maintain essential services.
Five business continuity priorities following the banking disruption
The November 16 incident provides an opportunity for executives to examine whether their organizations are adequately prepared for interruptions involving external technology providers and financial services.
Identify critical financial and operational dependencies
Businesses should document the applications, banking services, payment platforms, and integrations required to complete essential transactions. This assessment should identify which activities would be interrupted if a particular service became unavailable and whether alternative procedures could maintain operations temporarily.
Establish clear incident escalation procedures
Employees need to know whom to contact when financial transactions or business applications stop functioning. IT, finance, operations, and external providers should have clearly defined responsibilities for investigating problems, communicating updates, and determining when additional action is necessary.
Maintain reliable transaction reconciliation procedures
When payments are delayed, organizations need processes for confirming transaction status without accidentally creating duplicate payments or inaccurate financial records. Finance teams should understand how their banking and accounting platforms handle pending transactions, failed transfers, and delayed confirmations.
Test business continuity arrangements
Continuity plans should include scenarios involving unavailable banking services, payment-processing delays, cloud application outages, and failures affecting third-party integrations. Testing these scenarios helps identify weaknesses in communication, system access, and operational responsibilities before an actual disruption occurs.
Review technology vendor accountability
Organizations should understand which providers are responsible for maintaining critical systems, supporting integrations, and assisting during service interruptions. Service agreements should define relevant responsibilities, escalation channels, and support expectations so that technical problems can be investigated without unnecessary delays.
The financial risks of technology downtime extend beyond lost productivity
Technology disruptions are often evaluated according to the number of employees affected or the duration of service unavailability. However, the business consequences can extend into financial management, customer relationships, and operational decision-making.
A delayed transaction may require additional verification, while an unavailable application can interrupt billing, procurement, or customer service processes. Even after systems return to normal, employees may need to reconcile outstanding work and investigate discrepancies created during the interruption.
The extent of these consequences depends on the organization’s processes and the systems involved. Businesses with well-documented workflows, coordinated technology support, and established continuity procedures are generally better positioned to manage temporary interruptions than organizations that rely on improvised responses.
Executives should therefore consider technology resilience as part of financial and operational risk management. Investments in reliable infrastructure, application oversight, and recovery planning support more predictable operations and reduce avoidable uncertainty.
What the JPMorgan Chase disruption means for business leaders
The November 16 banking incident demonstrated that a technical failure within one organization can create consequences for customers and businesses using other providers. JPMorgan Chase identified a software bug affecting its transaction processing, while Zelle and several other financial institutions reported that their own systems remained operational.
The incident was not a confirmed cyberattack, nor was it evidence of a systemic banking failure. Its significance lies in the dependencies connecting modern financial services and the operational difficulties that can emerge when one component becomes temporarily unreliable.
For mid-sized organizations, the lesson extends well beyond banking. Cloud platforms, financial applications, communication systems, and external software providers all form part of the technology infrastructure supporting daily business operations.
Organizations cannot prevent every outage affecting an external provider, but they can improve their readiness through proactive IT management, documented system dependencies, coordinated vendor relationships, and tested business continuity procedures.
As business technology becomes increasingly interconnected, operational resilience depends on more than maintaining individual systems. It requires understanding how those systems work together, identifying the consequences of failure, and establishing the processes needed to keep essential business functions operating when unexpected disruptions occur.
Sources and references
1. Reuters, November 16, 2026. JPMorgan says software bug slows its transactions.
https://www.investing.com/news/stock-market-news/downdetector-reports-outages-major-us-banks-5030747
2. Associated Press, November 16, 2026. A technical issue at JPMorgan Chase triggers online banking delays for major US banks.
https://www.seattlepi.com/business/customers-nation-s-largest-banks-reporting-a22533729
3. ABC News, November 17, 2026. JPMorgan Chase reporting technical issue, delays with transactions.
https://www.goodmorningamerica.com/news/story/us-banks-reporting-technical-issues-online-transactions-138187551/
4. ABC News Australia, November 17, 2026. What to know about the online banking delays affecting major US banks.
https://www.abc.net.au/news/2026-11-17/online-banking-delays-us-banks/107395034

Anantha Nageswaran is the chief editor and writer at TheBusinessBlaze.com. He specialises in business, finance, insurance, loan investment topics. With a strong background in business-finance and a passion for demystifying complex concepts, Anantha brings a unique perspective to his writing.